GLM-5.3 Found 2,436 Real Vulnerabilities
GLM-5.3 found 2,436 vulnerabilities across 269 projects, with real CVEs in Linux and WebKit. Then Z.ai took the public ledger down. What we recorded.
GLM-5.3 cybersecurity capability is the reason Z.ai gave for holding the model's weights back at launch. Working with security teams in China, Z.ai says it identified 2,436 vulnerabilities across 269 open source projects, and for about two weeks it published a live public ledger of them. That ledger has since been taken down.
Key Takeaways:
- 2,436 findings, 1,097 of them critical or high severity, across 269 open source projects
- Only 53 are publicly disclosed so far; 2,383 remain under embargo
- The oldest flaw dates to 1981, and the average vulnerability had survived 26.6 years before discovery
- The public ledger went dark on or before 28 August. Disclosure moved to China's CNVD, CNNVD and NVDB platforms
- Real CVEs are already published against Linux, WebKit, FreeBSD, GStreamer, Suricata and Joomla
- Z.ai calls the capability emergent: it added vulnerability data expecting incremental gains and got a jump
Z.ai's own framing is unusually restrained for a launch post. It describes the security capability as developing "faster than we expected" during post-training scaling, and it is candid that the closed frontier remains ahead where exploitation gets deepest. The ledger at cvd.z.ai was the part worth your attention, because for a fortnight it turned a marketing claim into something you could check line by line. The figures below were recorded from it on 14 August, while it was still public.
What Z.ai claims, and how it measured it
The capability arrived as a side effect. Z.ai added vulnerability discovery data and environments to the post-training mix expecting the model to get better at spotting isolated flaws, and what it got instead was a model reasoning across multiple stages of exploitation and forming plans for complete chains.
Three benchmarks, covering different depths of the same problem:
| Benchmark | What it tests | GLM-5.2 | GLM-5.3 |
|---|---|---|---|
| CyberGym | Identify and validate vulnerabilities from white-box source | 77.2% | 84.5% |
| ExploitBench | Reason about real vulnerabilities and their exploitation | 24.4% | 54.4% |
| ExploitGym (2h / 6h) | Exploitation tasks completed under time budgets | 29 / 39 | 105 / 130 |
On CyberGym that 84.5% is the best published result, ahead of Mythos 5 at 83.8% and GPT-5.6 Sol at 83.6%. The pattern across all three is consistent and Z.ai spells it out: the further up the exploitation chain a benchmark sits, the bigger the jump from GLM-5.2, and the wider the remaining gap to closed models. Capability is growing fastest exactly where Z.ai is furthest behind.
One methodological detail deserves credit. ExploitGym results are time-normalised using per-model throughput from Artificial Analysis, so a faster model does not simply win by getting more attempts inside a fixed wall clock. Z.ai rescaled its own results by 115 tokens per second against Kimi K3's 40 and Qwen3.8 Max's 47, which cuts against its own numbers rather than flattering them.
Where GLM-5.3 still loses, by Z.ai's own table
Skipping this part would be dishonest, and Z.ai did not skip it. On ExploitBench, GLM-5.3's 54.4% sits well behind Mythos 5 at 78.0% and GPT-5.6 Sol at 76.5%. On ExploitGym, GLM-5.3 completes 105 tasks in two hours against Mythos 5's 181, and 130 in six hours against 247.
So the headline is not that an open-weights model just took the security crown. It is that an open-weights model got roughly half as good as the closed frontier at exploitation, in one post-training cycle, on unchanged base weights. The trajectory is the story; the absolute position is not.
Test an exploit-capable model somewhere you can afford to lose.
In two weeks these weights become something anyone can download and point at a codebase. The machine you evaluate that on should not be the one holding your production credentials. Zentor is a hosted cloud AI computer that runs separately from your desktop, alongside the tools you already use.
Try Zentor →The disclosure ledger was real, and then it wasn't
Most vendors would have stopped at the number. Z.ai built a public ledger that tracked each finding through the disclosure process, distinguishing what was already public from what was still under embargo, and recording the affected project, severity, CVE where one existed, and how long the flaw had sat in the codebase.
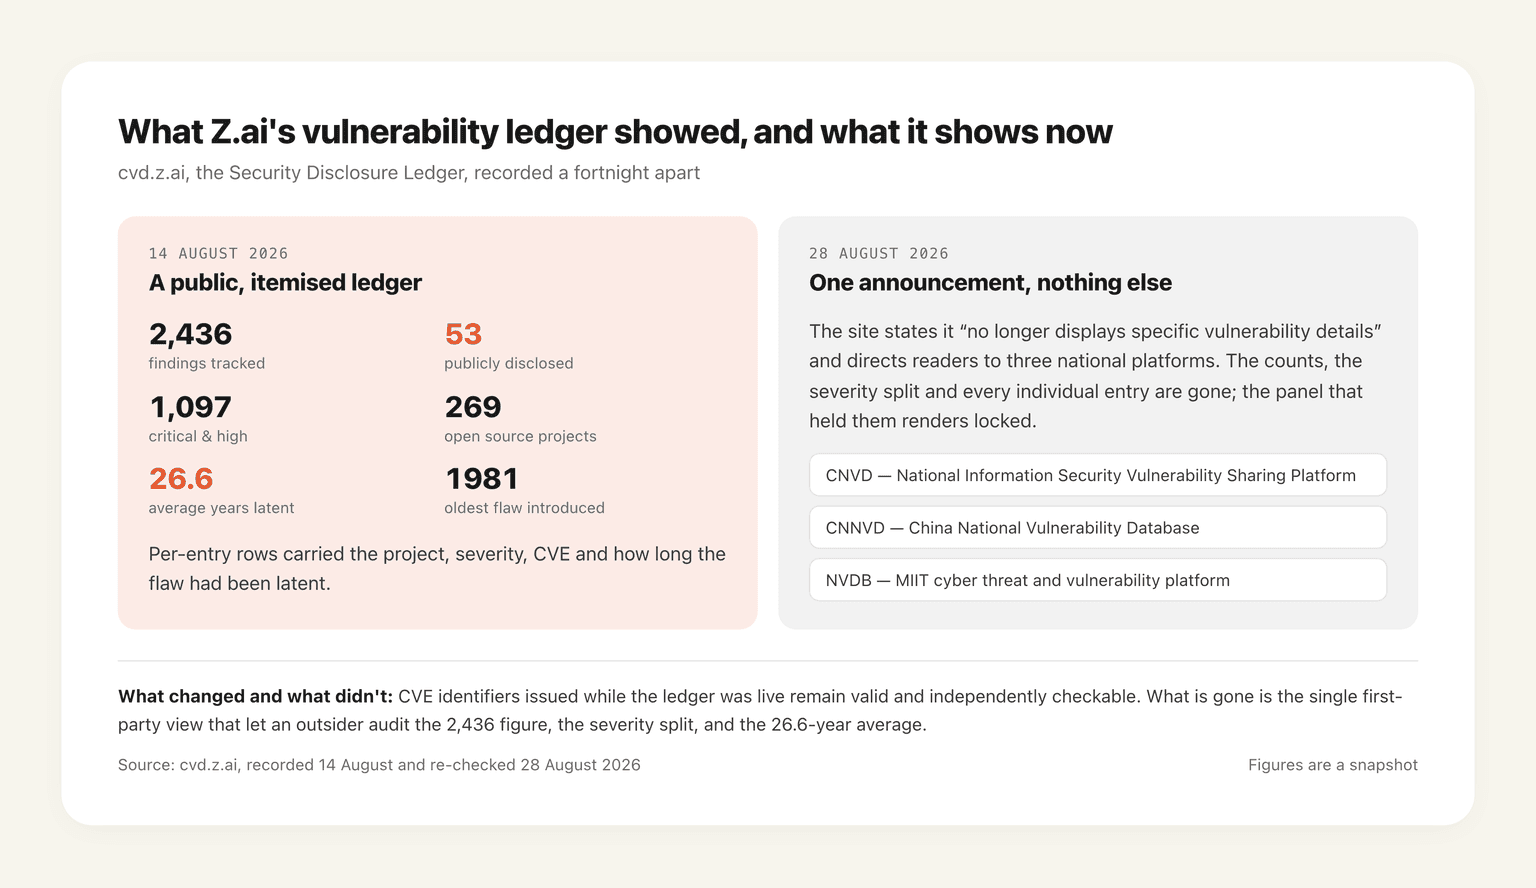
On 28 August 2026 that page carries a single announcement and nothing else: disclosure is moving to CNVD, CNNVD and NVDB, China's three national vulnerability platforms, and the site "no longer displays specific vulnerability details". The counts, the severity breakdown and the individual entries are gone, and the panel where they used to sit renders locked.
So the following figures are a snapshot, taken on 14 August 2026 while the ledger was live:
| Metric | Count |
|---|---|
| Findings tracked | 2,436 |
| Publicly disclosed | 53 |
| Under embargo | 2,383 |
| Critical and high | 1,097 |
| Open source projects covered | 269 |
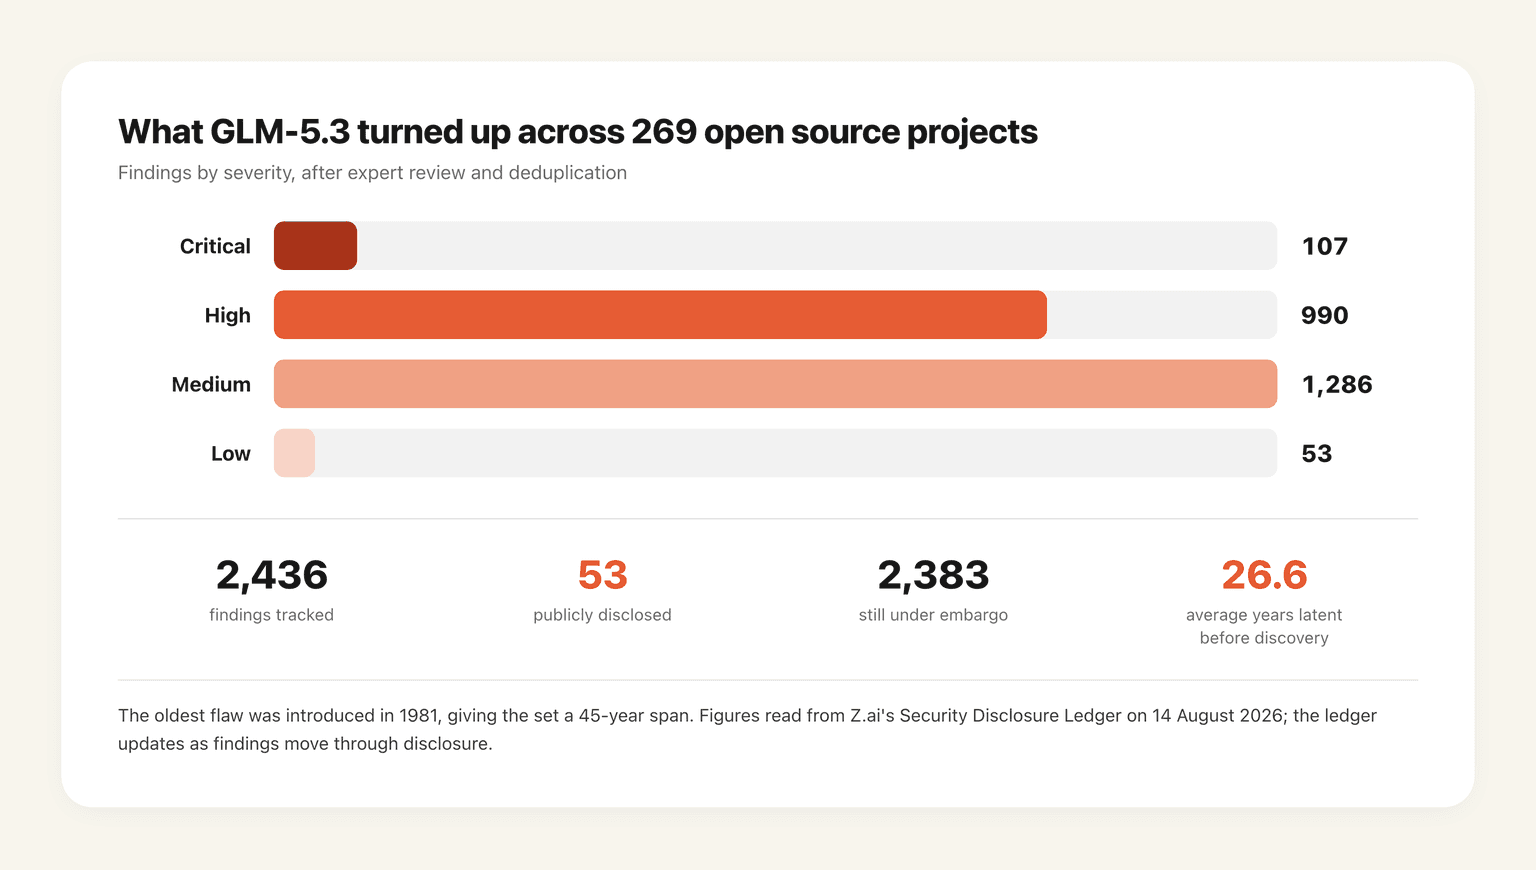
The severity split underneath broke down as 107 critical, 990 high, 1,286 medium and 53 low. Those numbers came after expert review, screening and deduplication by the security teams Z.ai worked with, which matters: raw model output on a task like this is mostly false positives, and the review step is where the claim earns or loses its credibility.
Worth being plain about what the takedown does and doesn't change. Moving disclosure to national platforms is a defensible process decision, and CVE identifiers already issued remain valid and checkable. What is lost is the single view that made the claim auditable by an outsider: nobody can now confirm the 2,436 figure, the severity split, or the 26.6-year average from a first-party page. A number you could verify for two weeks and cannot verify now is a weaker number, whatever the reason.
Six CVEs that show what it actually found
Abstract counts are easy to wave away, so here are named entries recorded from the ledger on 14 August, each carrying a published CVE. The CVE identifiers remain valid and can be looked up independently even though the ledger page no longer lists them:
| Project | Issue | CVE |
|---|---|---|
| Linux kernel | Use-after-free on an error path in 6lowpan NHC entries, latent 11 years | CVE-2026-64452 |
| Apple Safari (WebKit) | Memory handling flaw, crafted web content causes process crash | CVE-2026-43663 |
| FreeBSD | ptrace PT_SC_REMOTE missing argument validation, memmove underflow plus out-of-bounds sysent call |
CVE-2026-45253 |
| GStreamer | rfb_decoder_fill_rectangle() write granularity error causing heap out-of-bounds write |
CVE-2026-59691 |
| Suricata | SMTP MIME parser state not reset, allowing detection bypass | CVE-2026-57229 |
| Joomla | Stored XSS in com_installer update list via unescaped fields |
CVE-2026-48952 |
These are not toy targets. The Linux kernel, WebKit and FreeBSD are among the most heavily audited codebases in existence, reviewed continuously by people who are extremely good at this, and a model found live memory-safety bugs in all three.
The number that should actually worry you is 26.6
Not the 2,436. The average vulnerability in this set had been sitting in its codebase for 26.6 years before anyone noticed, and the oldest traces back to 1981, giving a 45-year span between the earliest flaw introduced and today.
Think about what that implies for the asymmetry. Decades of human review, fuzzing campaigns and static analysis passed over these bugs. One post-training cycle on a mid-size open model surfaced them in bulk. The backlog of undiscovered flaws in software everyone depends on is evidently much larger than the industry's discovery rate has ever suggested, and the tool that changes that discovery rate is about to be free to download.
Which cuts both ways, and I would resist the reflex to call this bad news. Defenders get the same capability, applied to their own code, before an attacker gets to it. That race just started, and the side with the source tree has a real head start.
Why the weights are two weeks late
Z.ai's commitment reads: the weights ship two weeks after launch, "once safety evaluation and hardening are complete." A promise with a condition attached rather than a date, and the security results above are the plain explanation for it.
The delay checks out against the source. On 14 August 2026 the zai-org organisation on Hugging Face had GLM-5.2, uploaded 2 July 2026, as its newest model, and the launch post's own HuggingFace button is a dead anchor labelled "Coming Soon". Nothing about GLM-5.3 is downloadable, whatever you may have seen advertised this week. We laid out all three access routes in what you can actually reach on launch day.
Two weeks is not long to harden anything, and Z.ai has not said what hardening means here or what would count as complete. Treat the date as intent.
What to do before an exploit-capable open model ships
If you maintain anything in a memory-unsafe language, the useful move is to run this class of tooling against your own code before someone else does, and the window to prepare is roughly two weeks. Prioritise the parsers: five of the six CVEs above sit in code that reads untrusted input, which is where this model's discovery pattern concentrates.
There is also a practical question about where you run the thing. An open-weights model tuned for vulnerability discovery, driven by an agent with shell access, is not software you want evaluating a codebase on the same laptop that holds your production credentials and an open email client. The general argument for that separation is in agent sandboxing explained, and it gets sharper when the model is specifically good at exploitation chains.
What GLM-5.3's security results change for open weights
The comfortable assumption until now was that frontier offensive capability stayed expensive, gated behind APIs with abuse monitoring on top. GLM-5.3 puts a serious fraction of it into a file you can download, and Z.ai is being about as responsible as a vendor can be on the way: staged release, safety evaluation first, a public ledger, findings routed through coordinated disclosure with 2,383 still held back.
That was a better model of behaviour than the industry norm, and the ledger going dark two weeks later takes some of it back. It does not change the destination. Two weeks from now the weights exist outside Z.ai's control permanently, and the 26.6-year figure says the supply of findable bugs is nowhere near exhausted. The interesting question stopped being whether AI can find real vulnerabilities; it can, and there are CVE numbers attached. The question now is who runs it against your dependencies first.
Zentor is built for the operational half of that: a hosted cloud AI computer that keeps running through a long scan and stays separate from the machine you work on, next to the tools you already use. The free trial runs three days on 1,000 credits, and a $20 subscription carries 1,000 credits a month.
FAQ
How many vulnerabilities did GLM-5.3 find?
Z.ai reports 2,436 vulnerabilities across 269 open source projects, after expert review, screening and deduplication with security teams in China. Of those, 1,097 are rated critical or high severity, split as 107 critical and 990 high. As of 14 August 2026, 53 were publicly disclosed and 2,383 remained under embargo.
Is GLM-5.3 better than other models at cybersecurity?
At vulnerability discovery, yes by Z.ai's measurements: 84.5% on CyberGym against Mythos 5's 83.8% and GPT-5.6 Sol's 83.6%. At exploitation it is clearly behind, scoring 54.4% on ExploitBench where Mythos 5 reaches 78.0%, and completing 105 ExploitGym tasks in two hours against Mythos 5's 181.
Where can I see the vulnerabilities GLM-5.3 found?
Not at cvd.z.ai any more. Z.ai's Security Disclosure Ledger published them until late August 2026, then replaced the listing with a notice directing readers to CNVD, CNNVD and NVDB, China's national vulnerability platforms. Individual CVE identifiers recorded while it was live, such as CVE-2026-64452 in the Linux kernel and CVE-2026-43663 in WebKit, remain valid and can be looked up elsewhere.
Why is Z.ai delaying the GLM-5.3 weights?
Z.ai says the weights ship two weeks after launch, once safety evaluation and hardening are complete. The model's jump in exploitation capability is the evident reason, though Z.ai has not defined what hardening involves or published a firm date.
What was the oldest vulnerability GLM-5.3 found?
One introduced in 1981, giving the set a 45-year span. Across all 2,436 findings the average flaw had been present for 26.6 years before discovery.
Can GLM-5.3 write exploits?
Z.ai's own benchmarks show it reasoning across multi-stage exploitation chains, scoring 54.4% on ExploitBench and completing 130 ExploitGym tasks within a six-hour budget. It is markedly weaker than closed frontier models at this, and Z.ai is holding the weights pending safety work partly for that reason.
Vulnerability counts, severity splits and CVE identifiers were read off Z.ai's Security Disclosure Ledger at cvd.z.ai on 14 August 2026, while that ledger was public. Re-checked 28 August 2026: the ledger no longer publishes entries and points to CNVD, CNNVD and NVDB instead, so the figures here can no longer be verified against the original source. Benchmark figures come from the GLM-5.3 launch post, which is unchanged.
Zentor Editorial Zentor editorial team
The Zentor editorial team writes about workflow automation, AI agents, and the tools we build. Default byline for industry overviews, listicles, and collaborative pieces.
Turn insights into action.
Zentor automates the recurring work your analysis points to. No engineering required.
References Z.ai Security Disclosure Ledger · GLM-5.3: Frontier Coding with Emergent Cyber Capabilities (Z.ai) · GLM-5.3 model overview, Z.ai developer documentation · zai-org on Hugging Face · slime, Z.ai's open-source RL post-training framework